AI Agent Reliability: 5 Honest Checks After 20-Run Tests
Two-thirds of failed agent runs ended with no error. Here is how I check the files instead of trusting the summary.

Two-thirds of failed agent runs ended with no error. Here is how I check the files instead of trusting the summary.
OpenAI cut the rate by 80% and gave up about two benchmark points. What that trade changes for a one-person stack.
Ember-1 cuts thinking by 71.3% at the same published price. What that actually changes for a one-person agent stack.
Hugging Face shipped native GGUF support on September 22. What 40 tokens per second means for a one-person local stack.
Anthropic’s new flagship got faster and cheaper on the same day. Here is what I checked before reacting.
OpenAI now runs the Codex harness for you. US-only retention is the line my client work still cannot cross.
OpenAI pulls its models from Cursor on November 12. What that really breaks in a one-person coding setup.
Replit’s credit-free build mode arrived August 19. What it changes for a one-person shop, and what it quietly doesn’t.
Google cut the price in half and posted a real coding benchmark jump. Here’s whether it’s worth switching for.
A 253-line agent framework just beat two bigger ones on a real coding benchmark. Here’s why that matters.
Eight weeks in, Google Antigravity still shares my coding stack with Claude Code, but only for specific jobs.
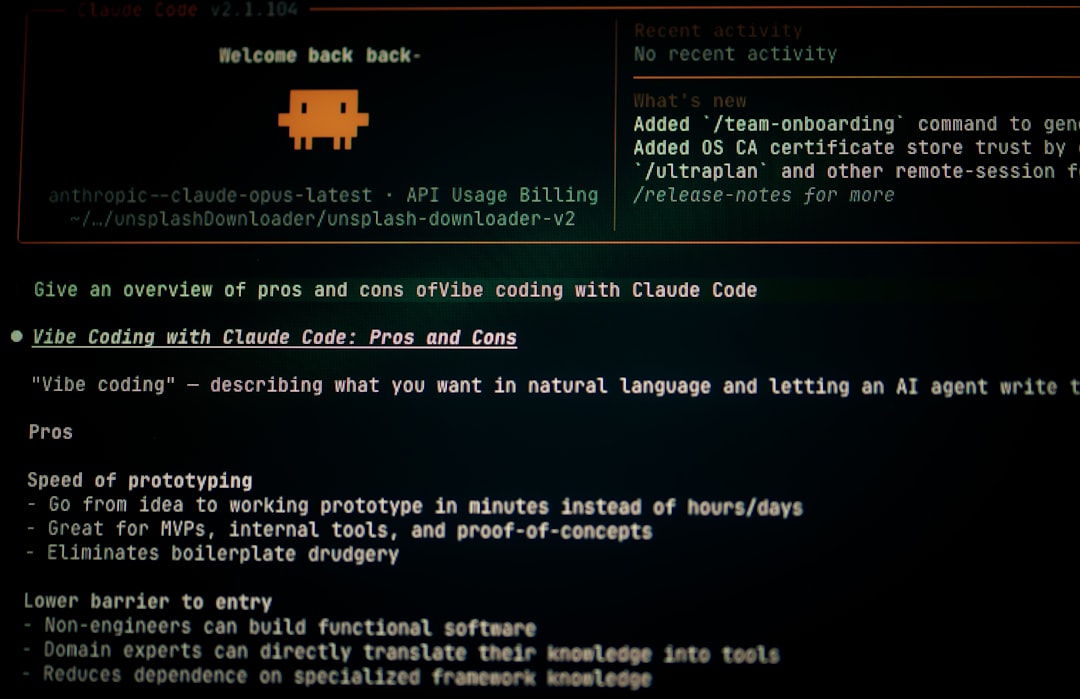
Six months on Claude Code, Max plan: the five automation wins that stuck, and the setup tax no one warns you about.